# Fine-Grained Cross-Modal Alignment for Unlinked Visual References in Scientific Papers
Ruyi Zhang, et al. · Ready for Submission · First Author
# Motivation
Matching a citation sentence to the figure or table it refers to is a basic step in academic document understanding. Most prior work takes a shortcut: it reads the figure number (“as shown in Figure 3”). That shortcut collapses when numbers are hidden, and the model has to actually understand the visual content.
We formalize this as number-free figure matching: given an anonymised citation sentence and all candidate figure/table images of a paper, predict which one is being cited.
# Benchmark
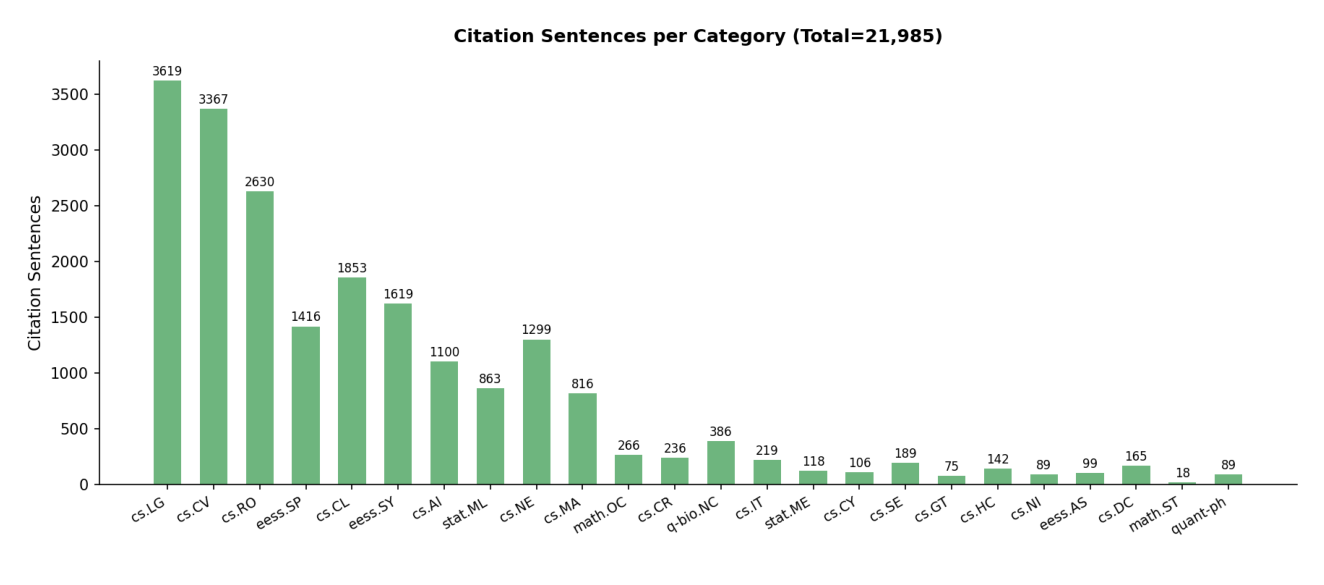
We build a benchmark of 1,165 arXiv papers across 30+ disciplines, containing 21,985 citation–figure pairs. Baseline MLLMs score only 35–52%, barely above random on long papers.
# Method
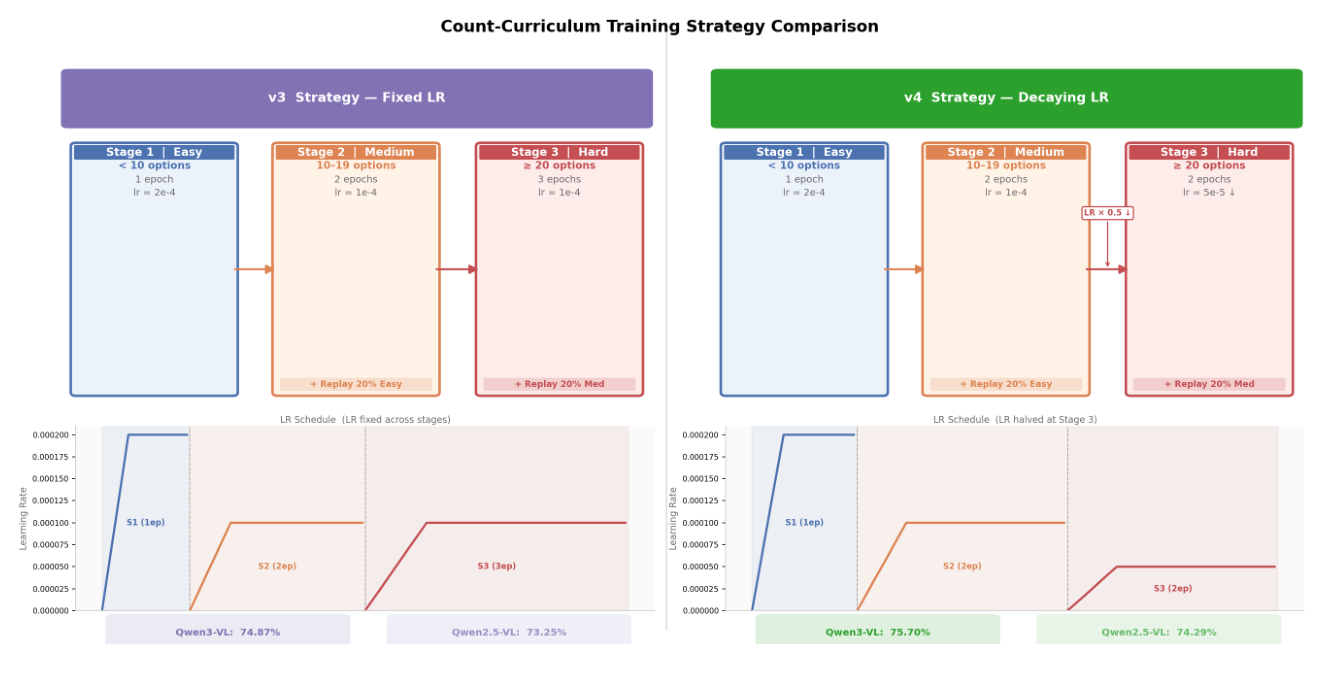
Count-Curriculum is a three-stage, difficulty-progressive fine-tuning strategy:
- Training samples are partitioned by the number of candidate options: Easy (< 10), Medium (10–19), Hard (≥ 20).
- The model is trained from easy to hard, replaying previous-stage data to prevent catastrophic forgetting.
- Combined with type-conditioned inference and a learning-rate decay schedule (v4).
# Results
Count-Curriculum v4 with Qwen3-VL-8B reaches 75.70% overall accuracy on the anonymised test set – +23.4 pp over the Qwen3-VL baseline and +32.6 pp over Qwen2.5-VL. The largest gain is on hard samples (+24.6 pp vs. direct QLoRA fine-tuning).
Qwen3-VL QLoRA Curriculum Learning Document Understanding
# Fine-Grained Cross-Modal Alignment for Unlinked Visual References in Scientific Papers
Ruyi Zhang, et al. · 准备投稿・第一作者
# 研究动机
将引用句与其所指的图或表对应起来,是学术文档理解中的一项基础任务。以往的大多数工作走了捷径:直接读取图表编号(如 "如图 3 所示")。一旦编号被隐去,这条捷径便会失效,模型必须真正理解视觉内容。
我们将该问题形式化为无编号图表匹配:给定一条匿名化的引用句以及论文中所有候选图 / 表图像,预测其引用的是哪一个。
# 基准数据集
我们构建了一个涵盖 30 余个学科、1,165 篇 arXiv 论文的基准,共包含 21,985 对引用句–图表。基线多模态大模型的准确率仅为 35–52%,在长论文上几乎与随机猜测相当。
# 方法
Count-Curriculum 是一种三阶段、难度递进的微调策略:
- 按候选选项数量划分训练样本:简单(< 10)、中等(10–19)、困难(≥ 20)。
- 模型由易到难依次训练,并回放前一阶段的数据以防止灾难性遗忘。
- 结合类型条件推理与学习率衰减策略(v4)。
# 实验结果
基于 Qwen3-VL-8B 的 Count-Curriculum v4 在匿名化测试集上取得 75.70% 的总体准确率,比 Qwen3-VL 基线高 23.4 个百分点,比 Qwen2.5-VL 高 32.6 个百分点。提升最大的是困难样本(相比直接 QLoRA 微调提高 24.6 个百分点)。
Qwen3-VL QLoRA 课程学习 文档理解