# Hierarchical Semantic-Constrained Heterogeneous Graph for Audio-Visual Event Localization
Zhe Yang, Ruyi Zhang, Hongtao Chen, Wenrui Li, Hengyu Man · IEEE TIP · Under Review
# Problem
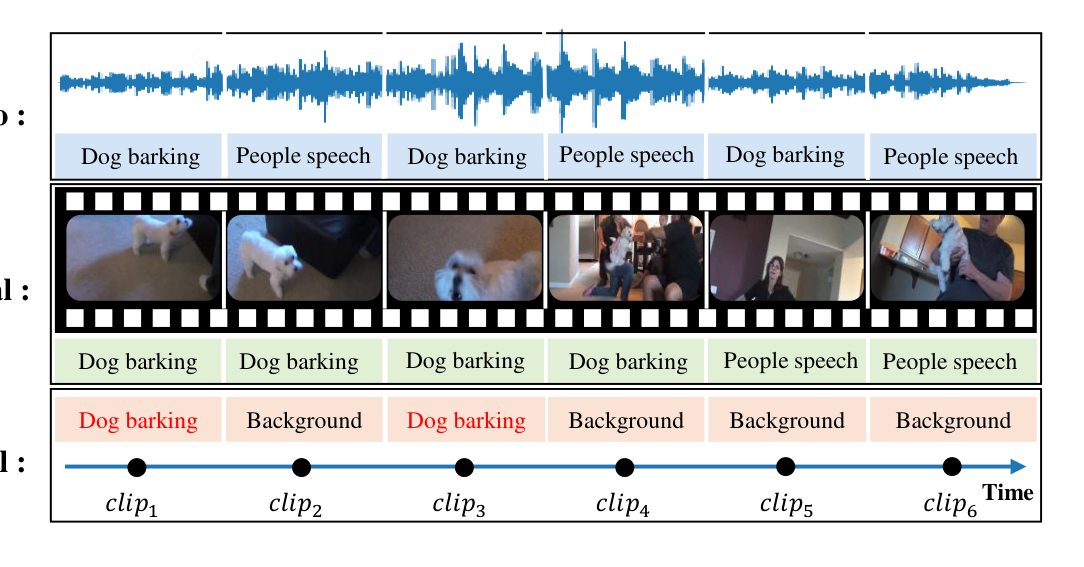
Open-vocabulary audio-visual event localization (OV-AVEL) jointly models audio and visual cues to recognize and temporally localize events, including categories unseen during training. Existing methods learn joint representations in Euclidean space and struggle with (1) keeping audio-visual consistency across temporal scales without supervision for unseen classes, and (2) keeping semantics consistent between segment and video levels.
# Method: HSCHG
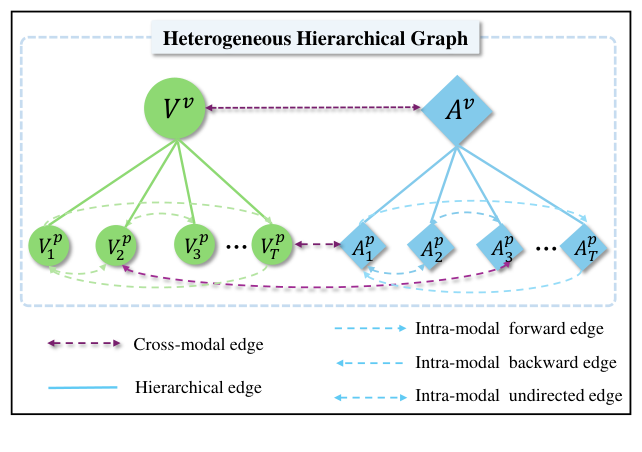
- A heterogeneous hierarchical graph with audio/visual segment nodes and video-level nodes, connected by multi-directional temporal edges.
- Dual-threshold gated fusion that only brings in cross-modal information when alignment confidence is high.
- Bidirectional semantic constraints between segment- and video-level representations.
- Multi-level audio-visual features and text prototypes are mapped into hyperbolic space, with a hierarchical entailment loss that models video-segment relations.
# My Contribution
Model validation, hyperbolic-space visualization and curation of the OV-AVEBench dataset.
# Hierarchical Semantic-Constrained Heterogeneous Graph for Audio-Visual Event Localization
Zhe Yang, Ruyi Zhang, Hongtao Chen, Wenrui Li, Hengyu Man · IEEE TIP・审稿中
# 研究问题
** 开放词汇音视频事件定位(OV-AVEL)** 联合建模音频与视觉线索,对事件进行识别和时序定位,其中也包括训练阶段未出现过的类别。现有方法在欧氏空间中学习联合表征,面临两方面困难:(1)在缺乏未见类别监督的情况下,难以保持跨时间尺度的音视频一致性;(2)难以保持片段级与视频级之间的语义一致性。
# 方法:HSCHG
- 构建异构层次图,包含音频 / 视觉片段节点与视频级节点,节点之间通过多方向时序边相连。
- 双阈值门控融合:仅在对齐置信度较高时引入跨模态信息。
- 在片段级与视频级表征之间施加双向语义约束。
- 将多层级音视频特征与文本原型映射到双曲空间,并通过层次蕴含损失刻画视频与片段之间的关系。
# 我的贡献
负责模型验证、双曲空间可视化,以及 OV-AVEBench 数据集的整理与构建。