Click a title to read the project post.
# First-Author Papers

ControlScene: Controllable Text-to-3D Scene Generation via Structured Layout Priors
Ruyi Zhang, et al.
CAAI Trans. · Accepted 3D Generation LLM
- The LayoutVerse-20K dataset with 20,000 manually annotated scenes (prompts, layouts, scene graphs, 3D scenes).
- An LLM-driven structured layout generation framework and two new metrics: category plausibility and layout plausibility.
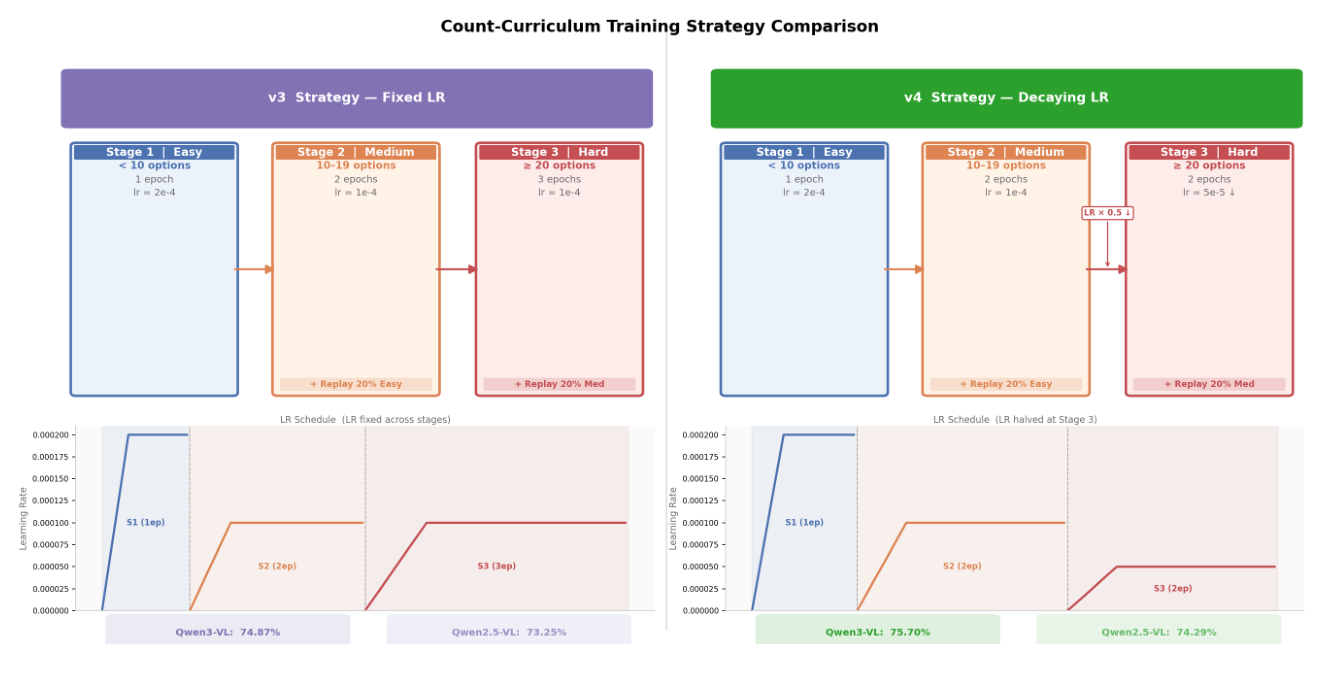
Fine-Grained Cross-Modal Alignment for Unlinked Visual References in Scientific Papers
Ruyi Zhang, et al.
Ready for Submission MLLM Document Understanding
- Count-Curriculum, a three-stage curriculum fine-tuning strategy that trains MLLMs from easy to hard figure-matching samples; reaches 75.70% accuracy on the number-free figure-matching task.
- A benchmark of 21,985 citation-figure pairs from 1,165 arXiv papers across 30+ disciplines.
# Co-Authored Papers
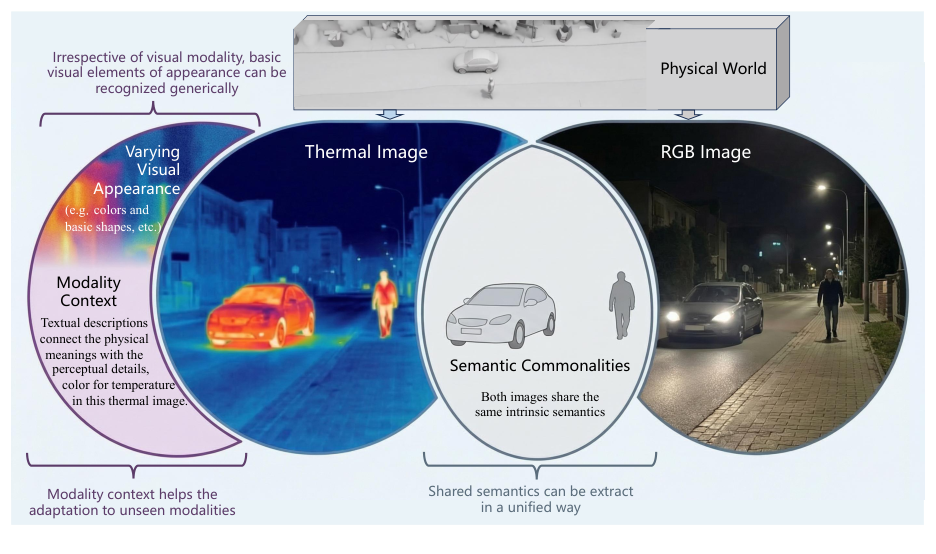
Generalize LMMs to Versatile Visual Modalities via Fabricated Modality Synthesis
S. Yuan, Y. Li, Ruyi Zhang, et al.
ECCV 2026 · Accepted LMM Generalization
- My role: design of the modality synthesis pipeline and zero-shot generalization experiments.
ScrollScape: Unlocking 32K Image Generation With Video Diffusion Priors
H. Yu, Y. Zhang, D. Di, Ruyi Zhang, et al.
ECCV 2026 · Accepted Diffusion Image Generation
- My role: ultra-high-resolution image generation and validation of the video diffusion prior module.

Task-Uncertainty-Aware Video Restoration for Time-varying Unknown Degradations
Wenrui Li, Hongtao Chen, Ruyi Zhang, Zhe Yang, Wangmeng Zuo
IEEE TMM · Accepted Video Restoration
- My role: validation of the spatio-temporal uncertainty regularization and quantitative comparison on multiple benchmarks.
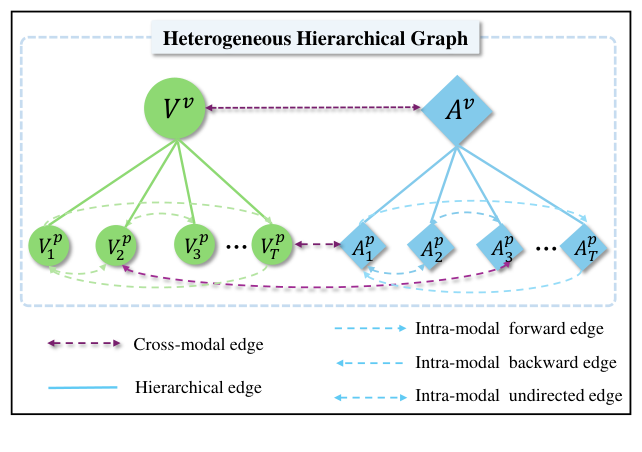
Hierarchical Semantic-Constrained Heterogeneous Graph for Audio-Visual Event Localization
Zhe Yang, Ruyi Zhang, Hongtao Chen, Wenrui Li, Hengyu Man
IEEE TIP · Under Review Audio-Visual
- My role: model validation, hyperbolic-space visualization and curation of the OV-AVEBench dataset.
点击论文标题即可阅读对应的项目介绍。
# 第一作者论文
ControlScene: Controllable Text-to-3D Scene Generation via Structured Layout Priors
Ruyi Zhang, et al.
CAAI Trans.・已接收 3D 生成 大语言模型
- 构建 LayoutVerse-20K 数据集,包含 20,000 个人工标注场景(文本提示、布局、场景图与三维场景)。
- 提出基于大语言模型的结构化布局生成框架,以及类别合理性与布局合理性两项新指标。
Fine-Grained Cross-Modal Alignment for Unlinked Visual References in Scientific Papers
Ruyi Zhang, et al.
准备投稿 多模态大模型 文档理解
- 提出 Count-Curriculum:一种三阶段课程微调策略,让多模态大模型由易到难学习图表匹配样本,在无编号图表匹配任务上达到 75.70% 的准确率。
- 构建包含 21,985 对引用句–图表的基准,数据来自 30 余个学科的 1,165 篇 arXiv 论文。
# 合作论文
Generalize LMMs to Versatile Visual Modalities via Fabricated Modality Synthesis
S. Yuan, Y. Li, Ruyi Zhang, et al.
ECCV 2026・已接收 LMM 泛化
- 本人工作:模态合成流程的设计与零样本泛化实验。
ScrollScape: Unlocking 32K Image Generation With Video Diffusion Priors
H. Yu, Y. Zhang, D. Di, Ruyi Zhang, et al.
ECCV 2026・已接收 扩散模型 图像生成
- 本人工作:超高分辨率图像生成,以及视频扩散先验模块的验证。
Task-Uncertainty-Aware Video Restoration for Time-varying Unknown Degradations
Wenrui Li, Hongtao Chen, Ruyi Zhang, Zhe Yang, Wangmeng Zuo
IEEE TMM・已接收 视频复原
- 本人工作:时空不确定性正则化的验证,以及在多个基准上的定量对比。
Hierarchical Semantic-Constrained Heterogeneous Graph for Audio-Visual Event Localization
Zhe Yang, Ruyi Zhang, Hongtao Chen, Wenrui Li, Hengyu Man
IEEE TIP・审稿中 音视频
- 本人工作:模型验证、双曲空间可视化,以及 OV-AVEBench 数据集的整理与构建。